Breaking News
 A Tiny Step in the Right Direction
 More Than 5,500 NYC Teachers Fired Under COVID Vaccine Mandate, Attorney Says
 You Need to Watch This Before You Vote!! (Patrick Smith from 2016)...
 A particle collider just showed that matter can emerge from nothing inside a quantum vacuum
Top Tech News
 Jetson ONE personal eVTOL pod is about to go full sky patrol
 America's INSANE BREAKTHROUGH Could Replace Septic Tanks Forever
 Amazing DIY Building Material for Home & Yard - Inexpensive and Easy!
 Researchers have discovered a massive deposit of hidden water...
 Amazon's Ring Unveils Flying Drone And Robot To Patrol Homes And Businesses
 Anthropic Strikes $3.4 Billion Off-Grid Power Agreement to Bypass U.S. Grids, Reports Say
 The X-ray room just shrank to the size of a laptop
 Dead Simple Apocalypse Power: Build It in an Hour
 Gritt and MasTec partner to bring physical AI to solar construction sites
 Baby it's cold INSIDE! Scientists create the coldest temperature ever recorded in the lab...
"Reality" Edited in Real Time: New Tech Shows Why You Can't Trust Anything You See on
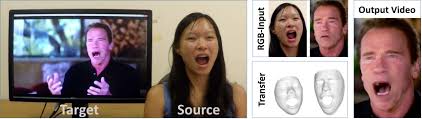
(Truthstream Media) Talk about wag the dog. I'm not even sure what to write for a description of the video you are about to watch.
 (Via Stanford University)
So-called "reality" can be edited in real-time.
It's the matrix.
The project is a joint effort in progress between Stanford, the Max Planck Institute for Informatics, and the University of Erlangen-Nuremberg. According to the project's abstract, via Stanford University:
We present a novel approach for real-time facial reenactment of a monocular target video sequence (e.g., Youtube video). The source sequence is also a monocular video stream, captured live with a commodity webcam. Our goal is to animate the facial expressions of the target video by a source actor and re-render the manipulated output video in a photo-realistic fashion. To this end, we first address the under-constrained problem of facial identity recovery from monocular video by non-rigid model-based bundling. At run time, we track facial expressions of both source and target video using a dense photometric consistency measure. Reenactment is then achieved by fast and efficient deformation transfer between source and target. The mouth interior that best matches the re-targeted expression is retrieved from the target sequence and warped to produce an accurate fit. Finally, we convincingly re-render the synthesized target face on top of the corresponding video stream such that it seamlessly blends with the real-world illumination.We demonstrate our method in a live setup, where Youtube videos are reenacted in real time.