Breaking News
 Russia warns NATO of a possible nuclear response if Kaliningrad exclave is cut off | DW News
 Now They're REALLY Mad
 More Americans are noticing the taste of their favorite snacks keep changing
 Eva: France is on fire. Hundreds of schools all over France are being besieged by second...
Top Tech News
 Med Beds Just Took a MASSIVE Step Forward, Healing People in Days!
 Palmer Luckey: Autonomous Weapons Are Ancient and Why Anduril Won't Build Humanoids | EP #295
 A laser just photographed objects through six feet of concrete
 Elon Musk's Next-Gen Motor Destroy Entire EV Industry
 China's disputed satellite refueling heralds new space war era
 BYD Will Put Solid-State Batteries In An EV Next Year: Executive
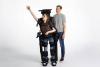 FDA-cleared exoskeleton puts spinal-cord patients back on their feet
 Your Robotic Vacuum Is Watching You -- Could It Someday Testify Against You in Court?
 Why Unigrid's Sodium-Ion Batteries Are the Game-Changer for Off-Grid Energy Storage
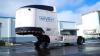 This Battery On Wheels Makes Any Diesel Truck Electric In 5 Minutes
GPT-4 Scores in Top 10% for Legal Bar Exam
GPT-4 can output 25000 words. GPT-4 can write a higher quality novel while GPT3.5 could only output a very short story.
GPT-4 can score 1410 on the SAT tests vs 1260 for GPT 3.5.
GPT-4 can score 161 on the LSAT vs 149 for GPT 3.5.
GPT-4 can score 99 percentil for GRE (high school equivalent) verbal test vs 63 percentile for GPT3.5.
GPT-4 is a Transformer based model pre-trained to predict the next token in a document. The post-training alignment process results in improved performance on measures of factuality and adherence to desired behavior. A core component of this project was developing infrastructure and optimization methods that behave predictably across a wide range of scales. This allowed us to accurately predict some aspects of GPT-4's performance based on models trained with no more than 1/1,000th the compute of GPT-4.
A large focus of the GPT-4 project was building a deep learning stack that scales predictably. The primary reason is that for very large training runs like GPT-4, it is not feasible to do extensive model-specific tuning. To address this, we developed infrastructure and optimization methods that have very predictable behavior across multiple scales. These improvements allowed us to reliably predict some aspects of the performance of GPT-4 from smaller models trained using 1, 000× –10, 000× less compute.